Menu

Solution

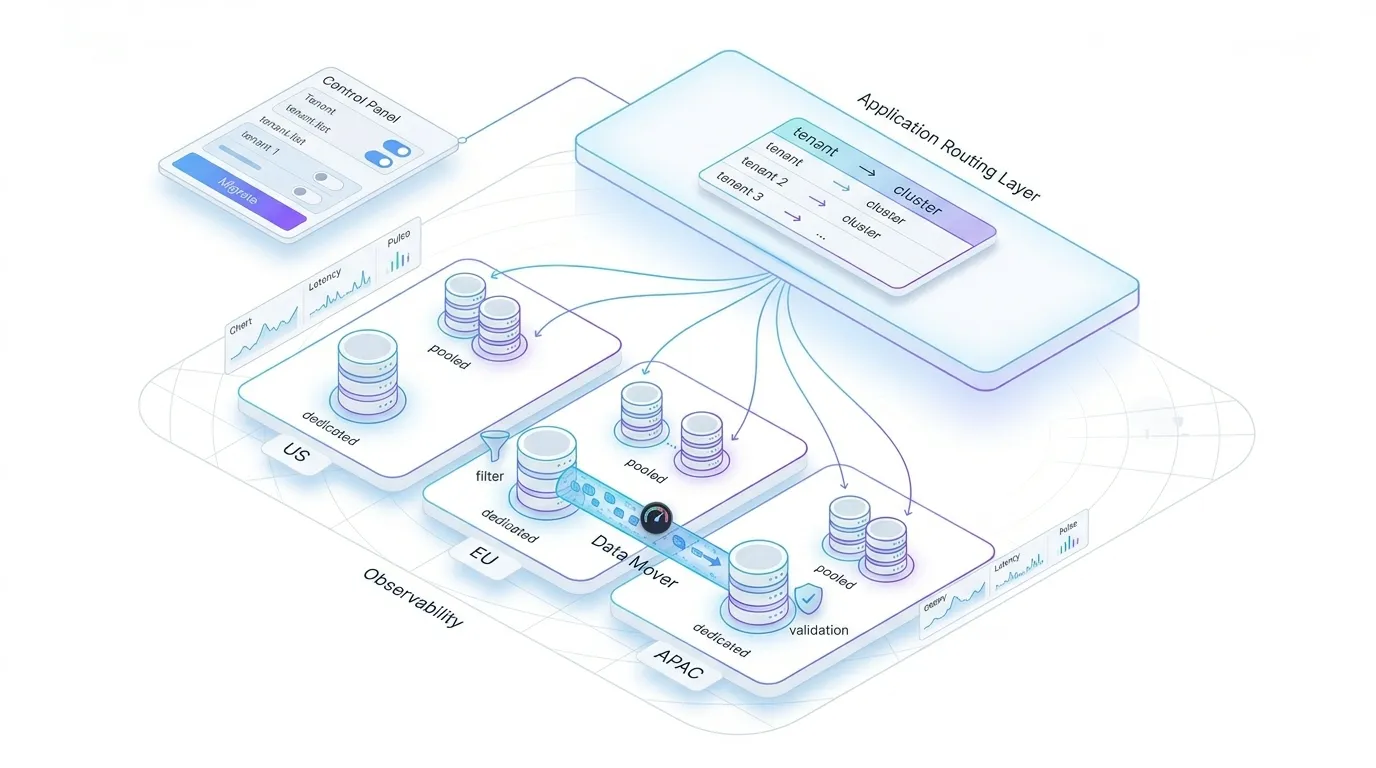
Replicate across clouds and regions

Keep a second copy of production data live in another cloud, another region, or another engine — for disaster recovery, for data locality, or so that a future migration is a cutover rather than a project.

What teams use this for

Disaster recovery

A warm copy in a second region or cloud, continuously up to date, with a measured lag you can actually quote in an RPO.

Data locality

Serve readers from the region they are in, or keep a jurisdiction's data inside it, without rewriting the application.

Migration readiness

Run the target in parallel until you trust it. When you switch, it is a cutover decision rather than a migration project.

What makes it hold up

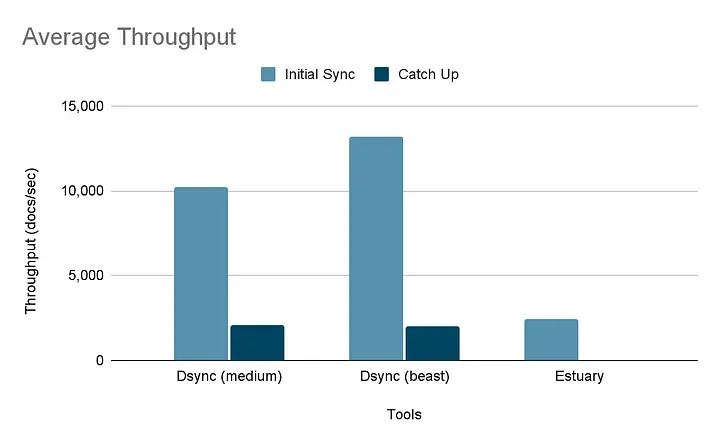
  • Sustains 1000+ operations per second on active workloads
  • Automatically resumes from the last checkpoint after an interruption
  • Runs in your infrastructure, not as a SaaS hop in the data path
  • Integrity checks run continuously, so drift surfaces early
  • No Kafka cluster to operate and no connector fleet to babysit
  • Reversible, so failover and failback are the same mechanism

See it running

What a migration actually looks like

Not a mockup. The command line, the web UI and the integrity check, from a real run.

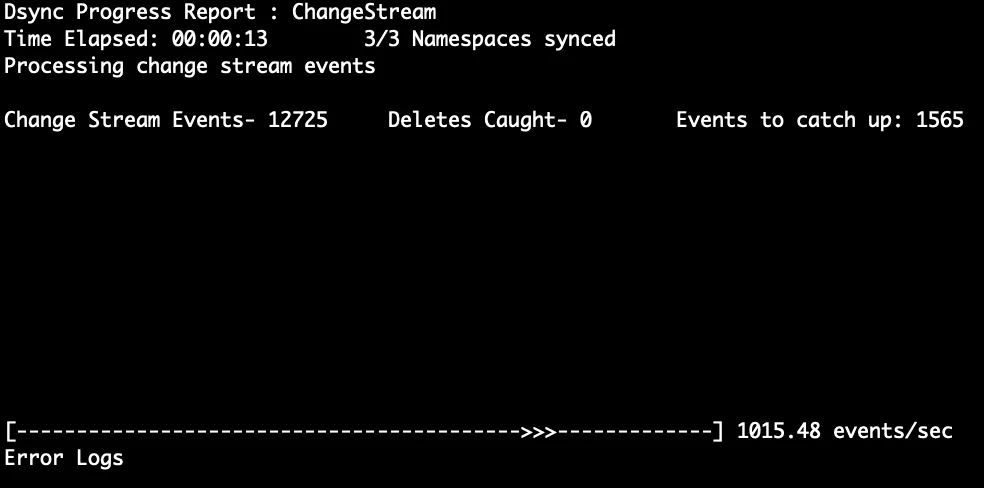
The dsync command-line interface during a migration, showing per-collection progress and throughput.
Command line — progress, throughput and lag per namespace, live.
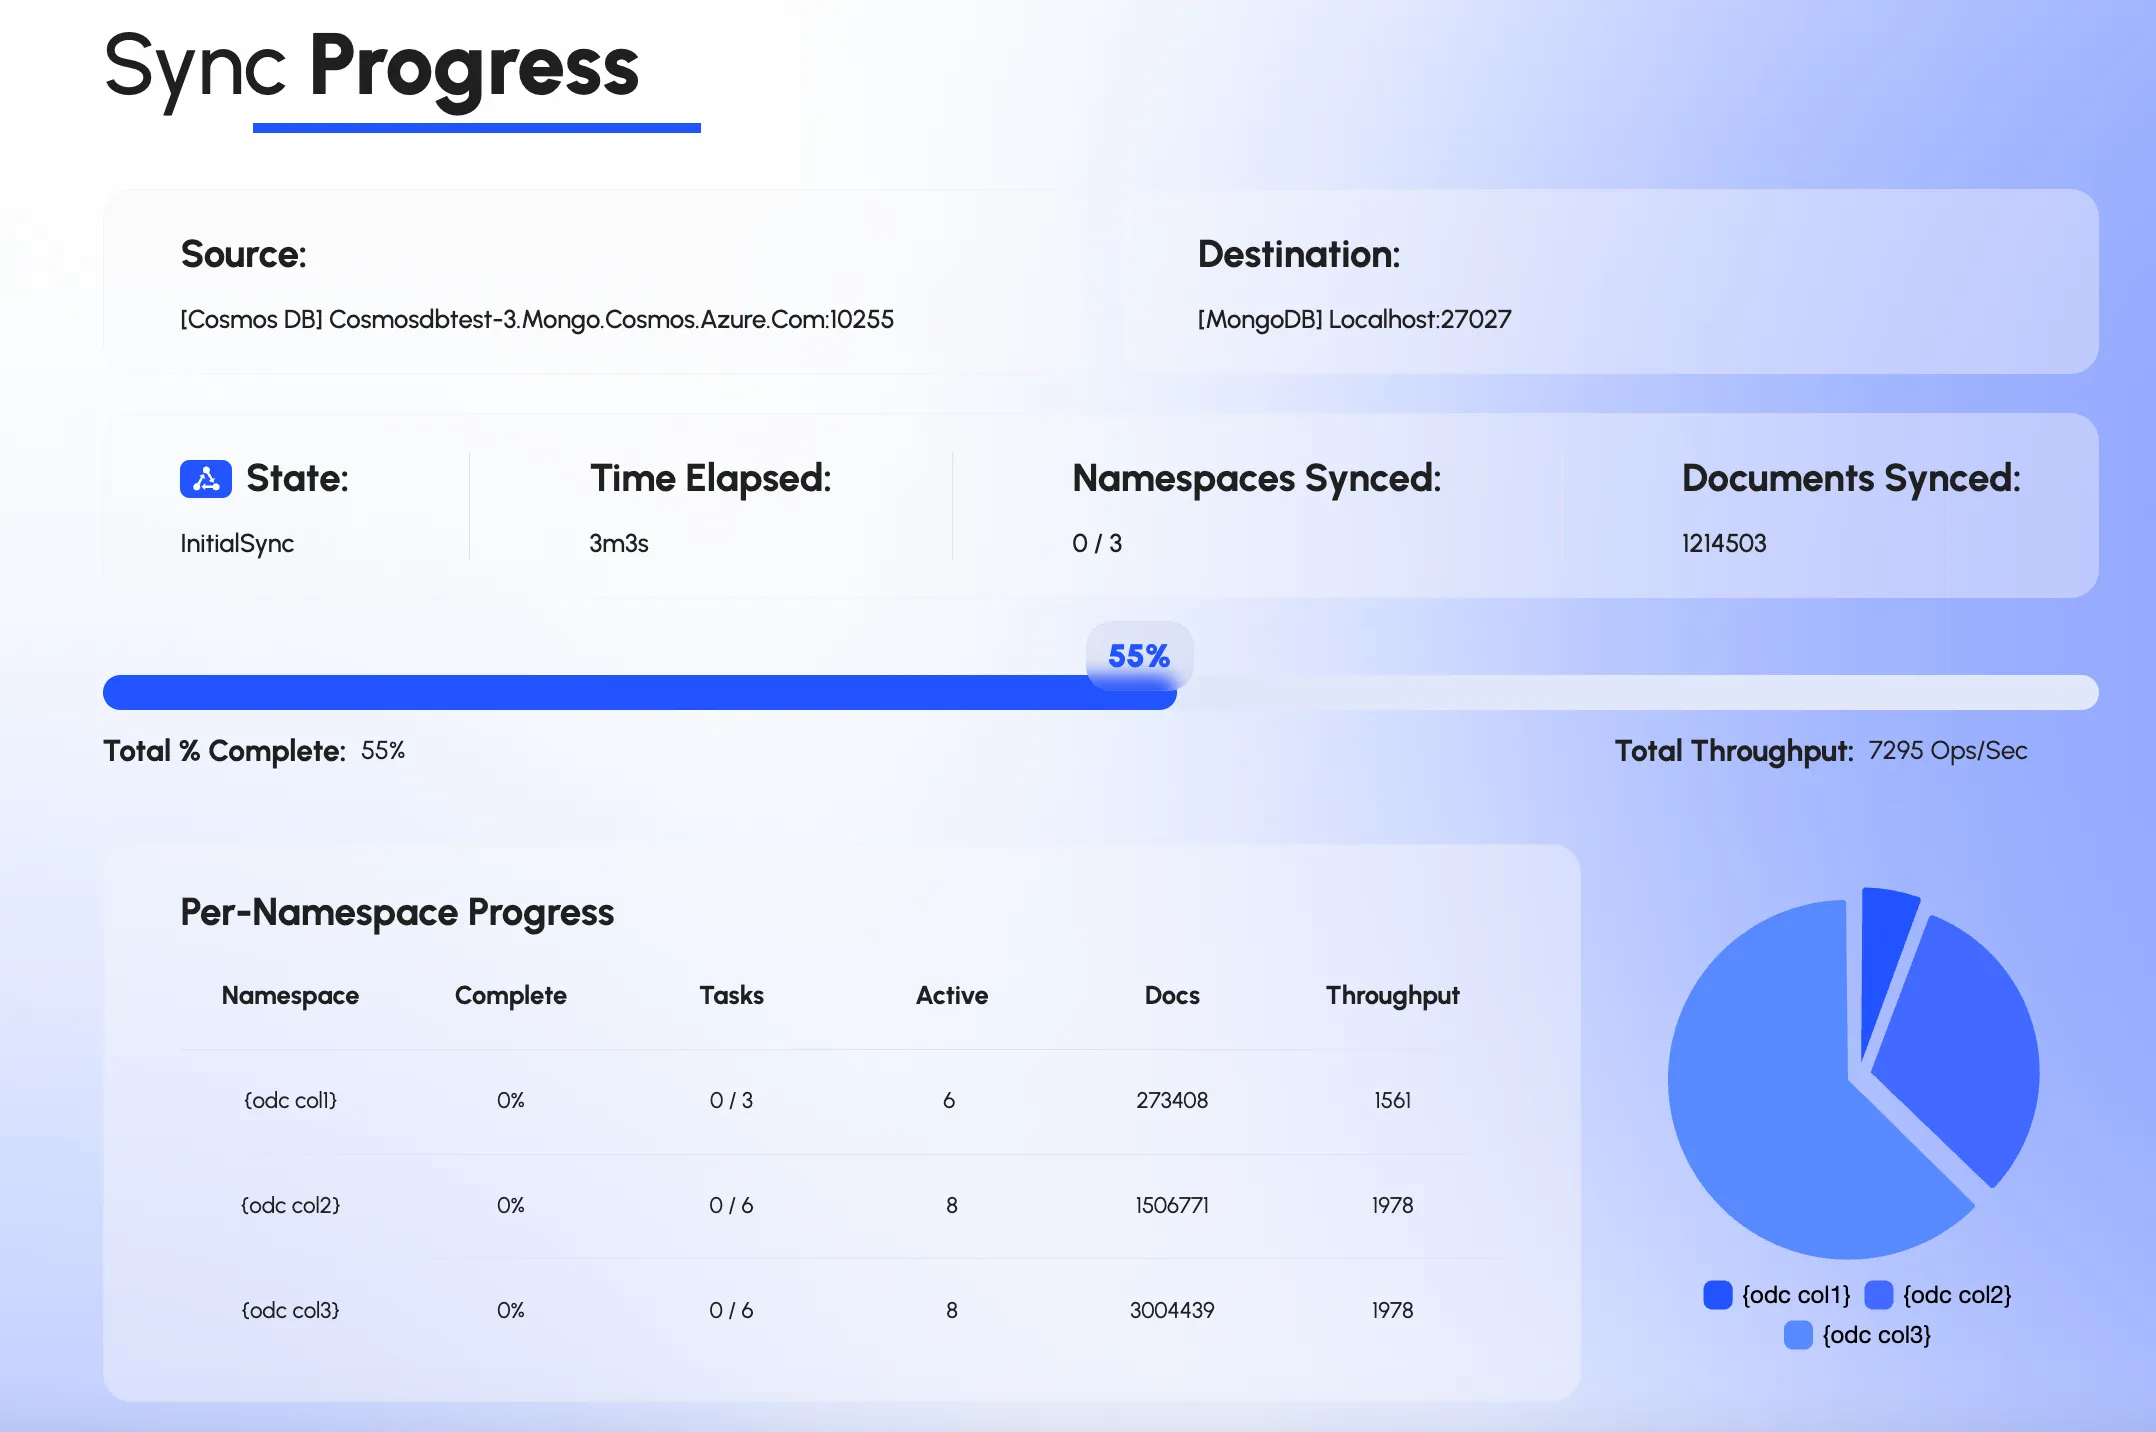
The dsync web interface showing a running migration with source, destination and status.
Web UI — the same run, for people who are not in a terminal.
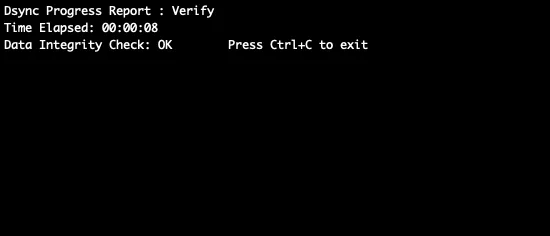
The dsync data integrity check comparing record counts and contents between source and destination.
Integrity check — evidence the two sides agree, before you cut over.

Supported systems

Proof

“The Adiom components, particularly dsync, worked extremely well for us and gave us all the peace of mind to confidently proceed with the cutover.”
VP Product and Data PlatformCatalina Marketing
1000+
Operations per second sustained during change data capture
Seconds
Replication lag
Reversible
Failover and failback are the same mechanism

More on replication at scale

Talk about your replication topology

Tell us the systems, the regions and the recovery objective. We will tell you what is achievable and what it takes to run.

We reply within one business day. Your details are handled per our privacy policy.